Listen, the software industry spends billions of dollars trying to build systems that are smarter than a line-by-line text scan, and every five years we crawl back to the terminal to run the exact same binary we used in 1989.
The Ephemeral Theater of Search
We have seen the cycle three times over. First it was localized XML parsers. Then it was enterprise search appliances that cost more than a Honda Civic. Then came the Elasticsearch era, followed by OpenTelemetry and Kibana dashboards that look like the bridge of the Starship Enterprise but take forty seconds to render a bar chart of HTTP 500 errors.
These tools are born out of a desire to escape the flat file. They want structure, schema, indexes, and cold-storage tiers. But structure requires maintenance. Schemas break when a developer decides a timestamp should include microseconds. Indexes corrupt when the root partition hits 100% capacity because someone forgot to rotate the debug logs.
When the site goes down at 3:00 AM, nobody opens the observability platform to write a structured JSON query. They SSH into the edge node, bypass the broken log forwarder, and run a utility that hasn’t changed its core interface since Ken Thompson wrote it on a PDP-11.
The Mechanical Sympathy of the Flat File
Why does grep win? It isn’t because we are stubborn. It’s because grep understands the hardware better than the frameworks that sit on top of it.
GNU grep does not read your file line by line using standard library input buffers. It avoids copying bytes altogether. It reads massive blocks into memory using raw system calls, searching for the needle using the Boyer-Moore algorithm, and only looking for newlines when it actually finds a match. It is so fast that, on modern NVMe drives, your search speed is limited by the kernel’s page cache, not the CPU.
But simplicity has its edge cases, and I still get tripped up by them. Just last week, I spent ten minutes wondering why a standard search on a log directory returned absolutely nothing, only to realize a crashing Go daemon had written a single null byte to the file. GNU grep quietly decided the entire 4GB file was binary and printed nothing but “Binary file matches” to standard output. I had to pass the text flag to get the trace:
grep -a -C 3 "connection reset" /var/log/nginx/error.logI have been doing this long enough to know that flag by heart, yet the muscle memory still failed me, and I stared at an empty terminal like a novice for too long.
The Text is the Truth
The modern observability stack wants us to believe that text files are a legacy format. They want structured JSON logs, tracing headers, and span IDs. They tell us that raw text doesn’t scale.
What they forget is that text is the universal interface of Unix. A JSON log is great until the parser encounters an unescaped double quote and drops the entire line. A database-backed log index is fantastic until the database itself is the thing that crashed.
When the system is degraded, the tool you use to diagnose the failure must not share dependencies with the failure itself. grep has no dependencies. It doesn’t need a JVM. It doesn’t need a Redis queue. It doesn’t need to resolve DNS. It takes raw bytes from standard input or a file descriptor, applies a regular expression, and dumps the result to standard output.
The frameworks will keep changing. We will rename log aggregation to observability, and we will rename search indices to vector databases. But under the hood, the bytes still hit the disk, and grep will still be waiting.
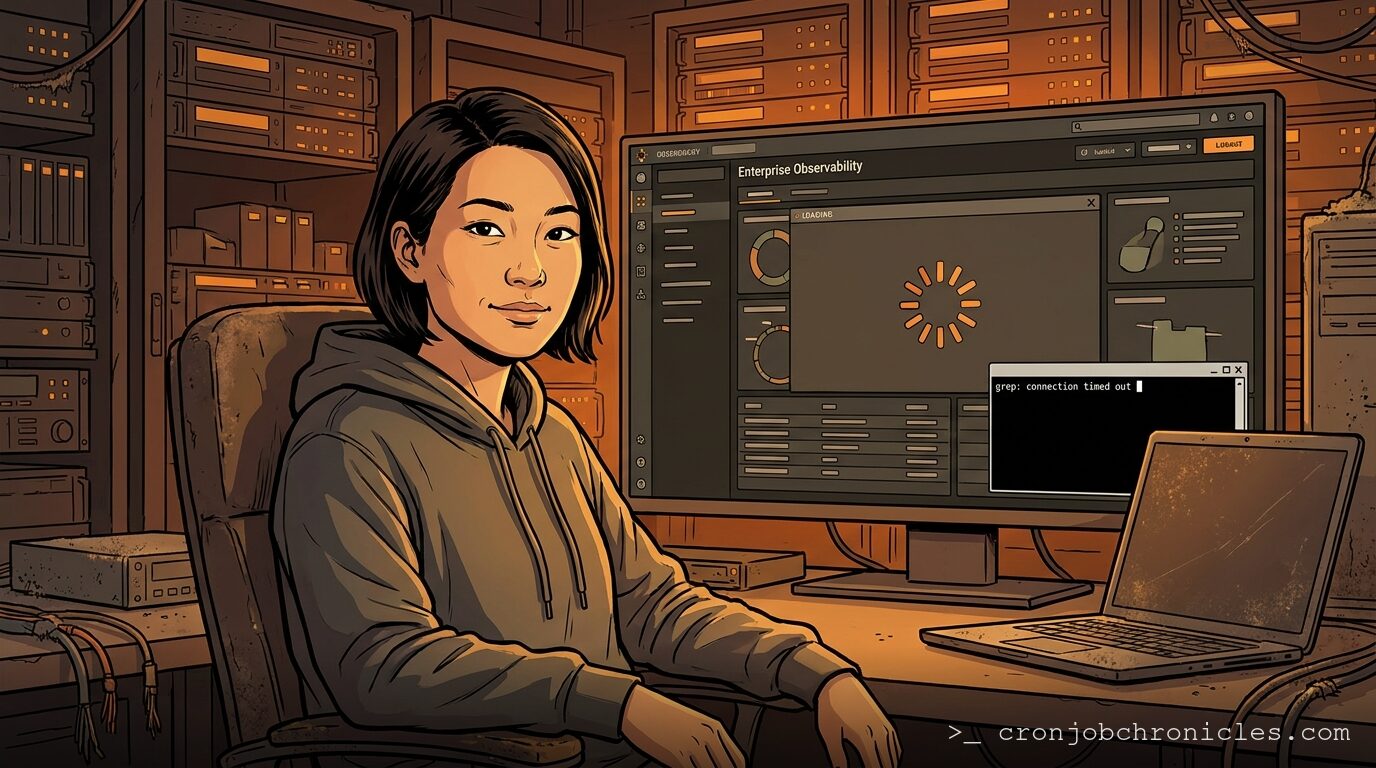
My terminal multiplexer flashes red in the corner. The load balancer is dropping connections, and the Grafana dashboard is currently spinning on a loading icon. I close the browser tab and type grep.